Jan-v1
A 4B reasoning model built on Qwen3-4B-thinking that scores 91.1% on SimpleQA, made for question answering and problem-solving.
Overview
- Parameters
- 4B
- Base model
- Qwen3-4B-Thinking
- Built for
- Reasoning and problem-solving
- License
- Apache 2.0
91.1%
SimpleQA accuracy
Jan-v1 is a 4B parameter model based on Qwen3-4B-thinking, designed for reasoning and problem-solving tasks. The model achieves 91.1% accuracy on SimpleQA through model scaling and fine-tuning approaches.
Try it in JanPerformance
SimpleQA Benchmark
Jan-v1 demonstrates strong factual question-answering capabilities:
| Benchmark | Jan-v1 | Perplexity Pro | Qwen3-4B-2507 | gpt-oss-20B | Jan-nano-128k | Jan-nano | Jan-nano (YaRN) | Lucy (YaRN) | DeepSeek-V3 | ChatGPT-4.5 | Baseline | Gemini-2.5-Pro | Claude-3.7-Sonnet | o3 | Grok-3 | o1 |
|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|
| SimpleQA (Question answering accuracy) | 91.1% | 90.6% | 86.5% | 86.3% | 83.2% | 80.7% | 79.7% | 78.3% | 78.2% | 62.5% | 59.2% | 52.9% | 50.0% | 49.4% | 44.6% | 42.6% |
At 91.1% accuracy, Jan-v1 outperforms several larger models on SimpleQA, including Perplexity's 70B model. This performance represents effective scaling and fine-tuning for a 4B parameter model.
Chat and Creativity Benchmarks
Jan-v1 has been evaluated on conversational and creative tasks:
| Benchmark | Jan-v1 | Qwen3-4B-Thinking | GPT-OSS-20B (High) | GPT-OSS-20B (Low) |
|---|---|---|---|---|
| EQBench | 83.61 | 82.61 | 78.35 | 78.35 |
| CreativeWriting | 72.08 | 65.74 | 30.23 | 26.38 |
| IFBench | 39.1 | 48.06 | 60.0 | 54.03 |
These benchmarks (EQBench, CreativeWriting, and IFBench) measure the model's ability to handle conversational nuance, creative expression, and instruction following.
Requirements
- Memory:
- Minimum: 8GB RAM (with Q4 quantization)
- Recommended: 16GB RAM (with Q8 quantization)
- Hardware: CPU or GPU
- API Support: OpenAI-compatible at localhost:1337
Using Jan-v1
Quick Start
- Download Jan Desktop
- Click Open in Jan above, or open the Hub and search for Jan-v1
- Choose a variant that fits your hardware, then click Download
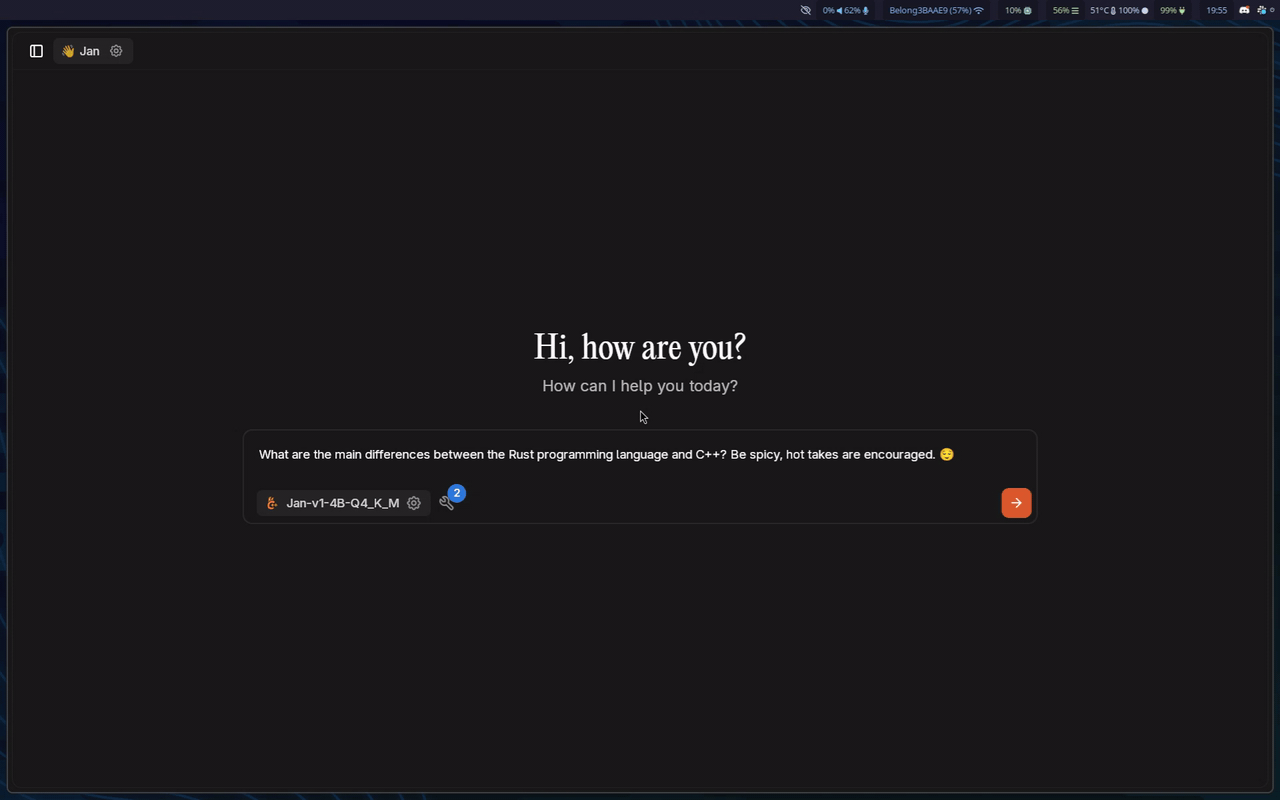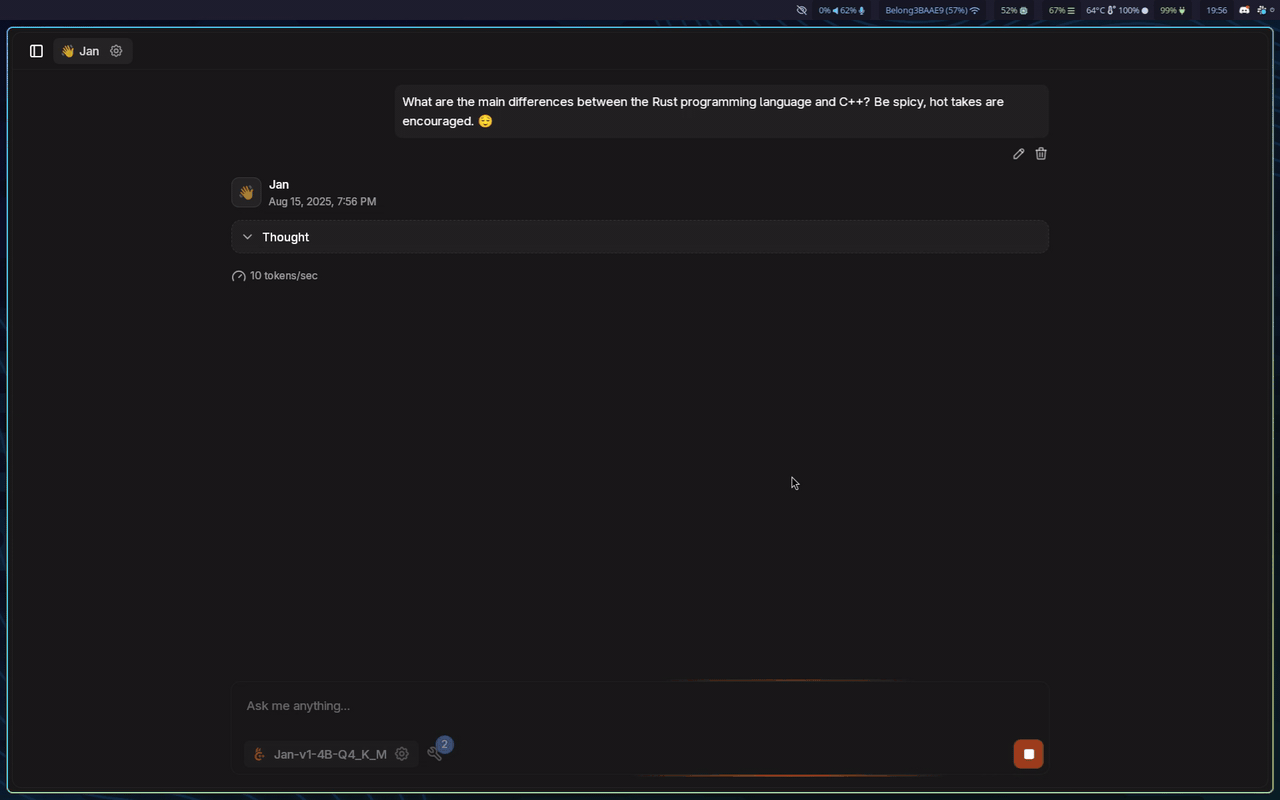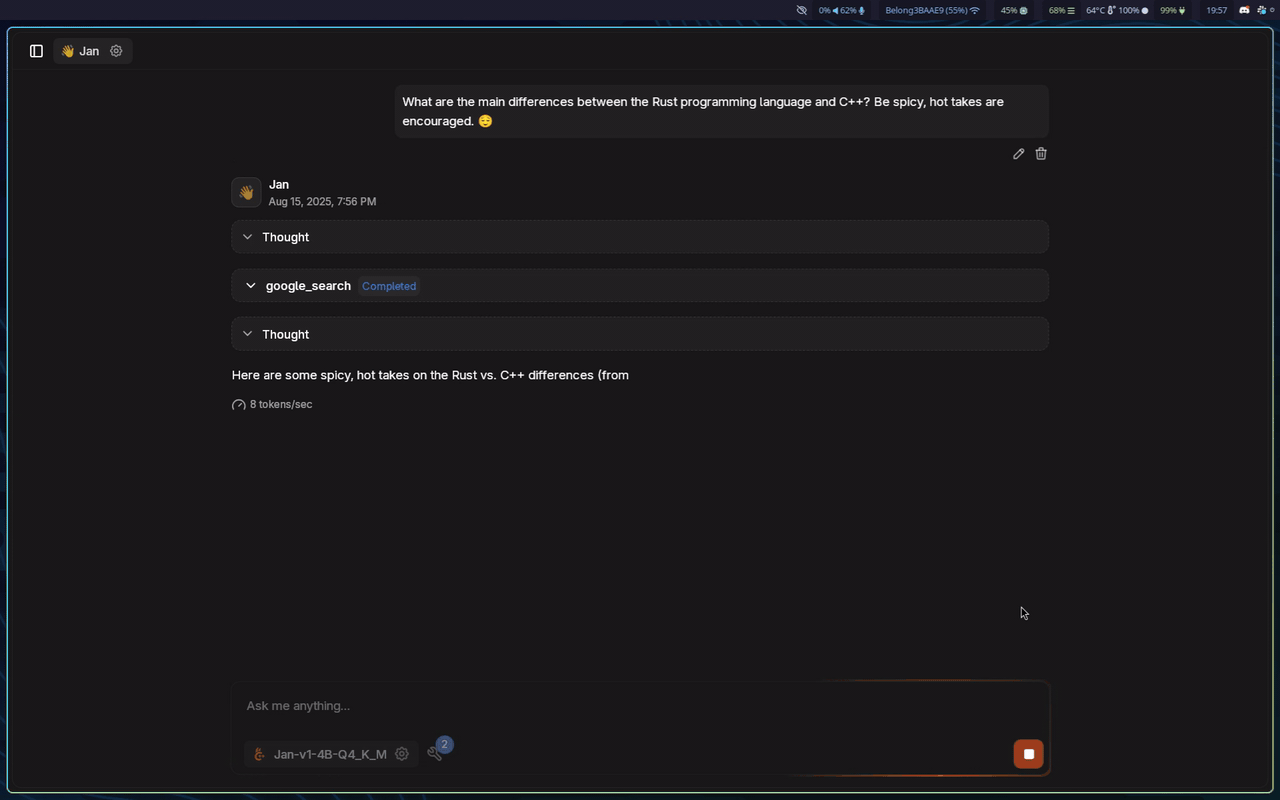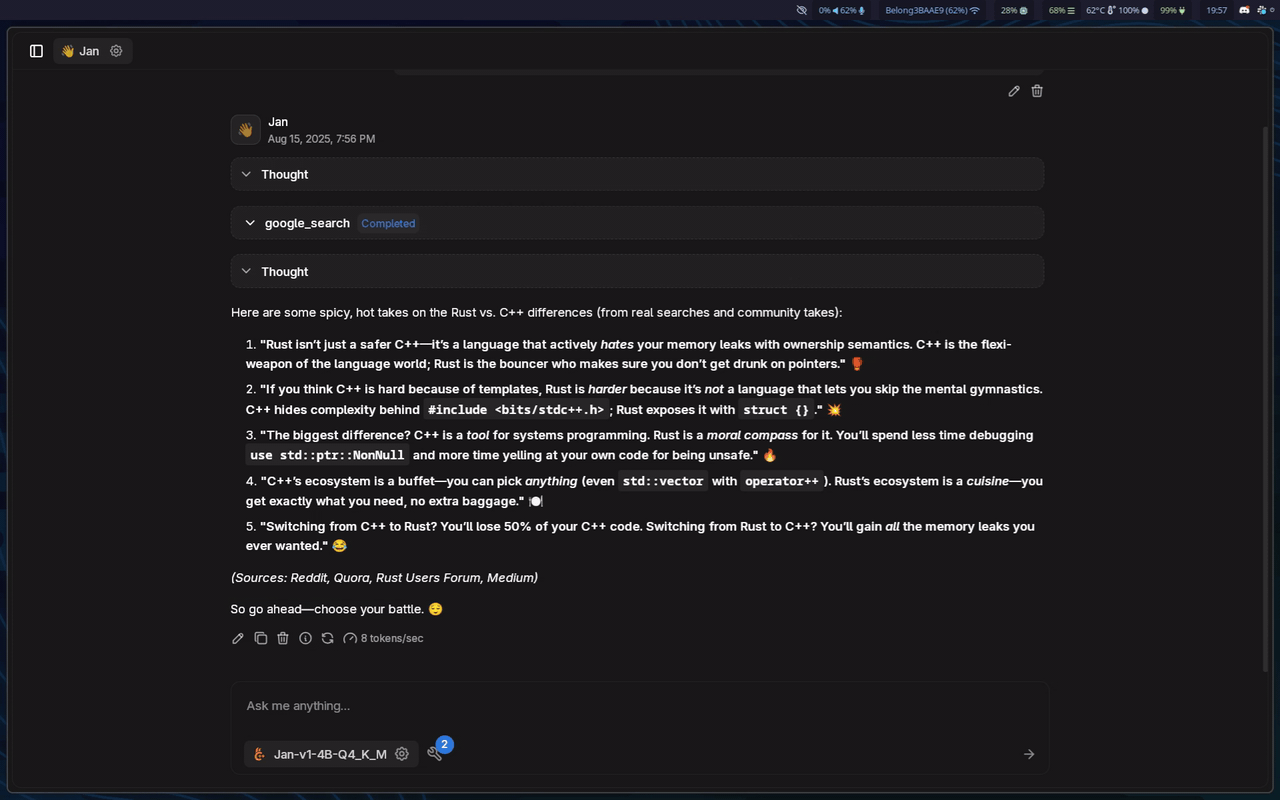
- Once downloaded, select Jan-v1 from the model selector in any chat
- Start chatting - no additional configuration needed
Demo
Deployment Options
Using vLLM:
vllm serve janhq/Jan-v1-4B \ --host 0.0.0.0 \ --port 1234 \ --enable-auto-tool-choice \ --tool-call-parser hermes
Using llama.cpp:
llama-server --model jan-v1.gguf \ --host 0.0.0.0 \ --port 1234 \ --jinja \ --no-context-shift
Recommended Parameters
temperature: 0.6top_p: 0.95top_k: 20min_p: 0.0max_tokens: 2048
What Jan-v1 Does Well
- Question Answering: 91.1% accuracy on SimpleQA
- Reasoning Tasks: Built on thinking-optimized base model
- Tool Calling: Supports function calling through hermes parser
- Instruction Following: Reliable response to user instructions
Limitations
- Model Size: 4B parameters limits complex reasoning compared to larger models
- Specialized Tasks: Optimized for Q&A and reasoning, not specialized domains
- Context Window: Standard context limitations apply
Downloads
- Jan: Download Jan
- Jan-v1-4B: Hugging Face (opens in a new tab) GGUF (opens in a new tab)
GGUF quantizations
- Q4_K_M: 2.5 GB - Good balance of size and quality
- Q5_K_M: 2.89 GB - Better quality, slightly larger
- Q6_K: 3.31 GB - Near-full quality
- Q8_0: 4.28 GB - Highest quality quantization
Talk to us
- Discussions: Hugging Face community (opens in a new tab)
- Chat: Discord (opens in a new tab)
- Issues: GitHub (opens in a new tab)